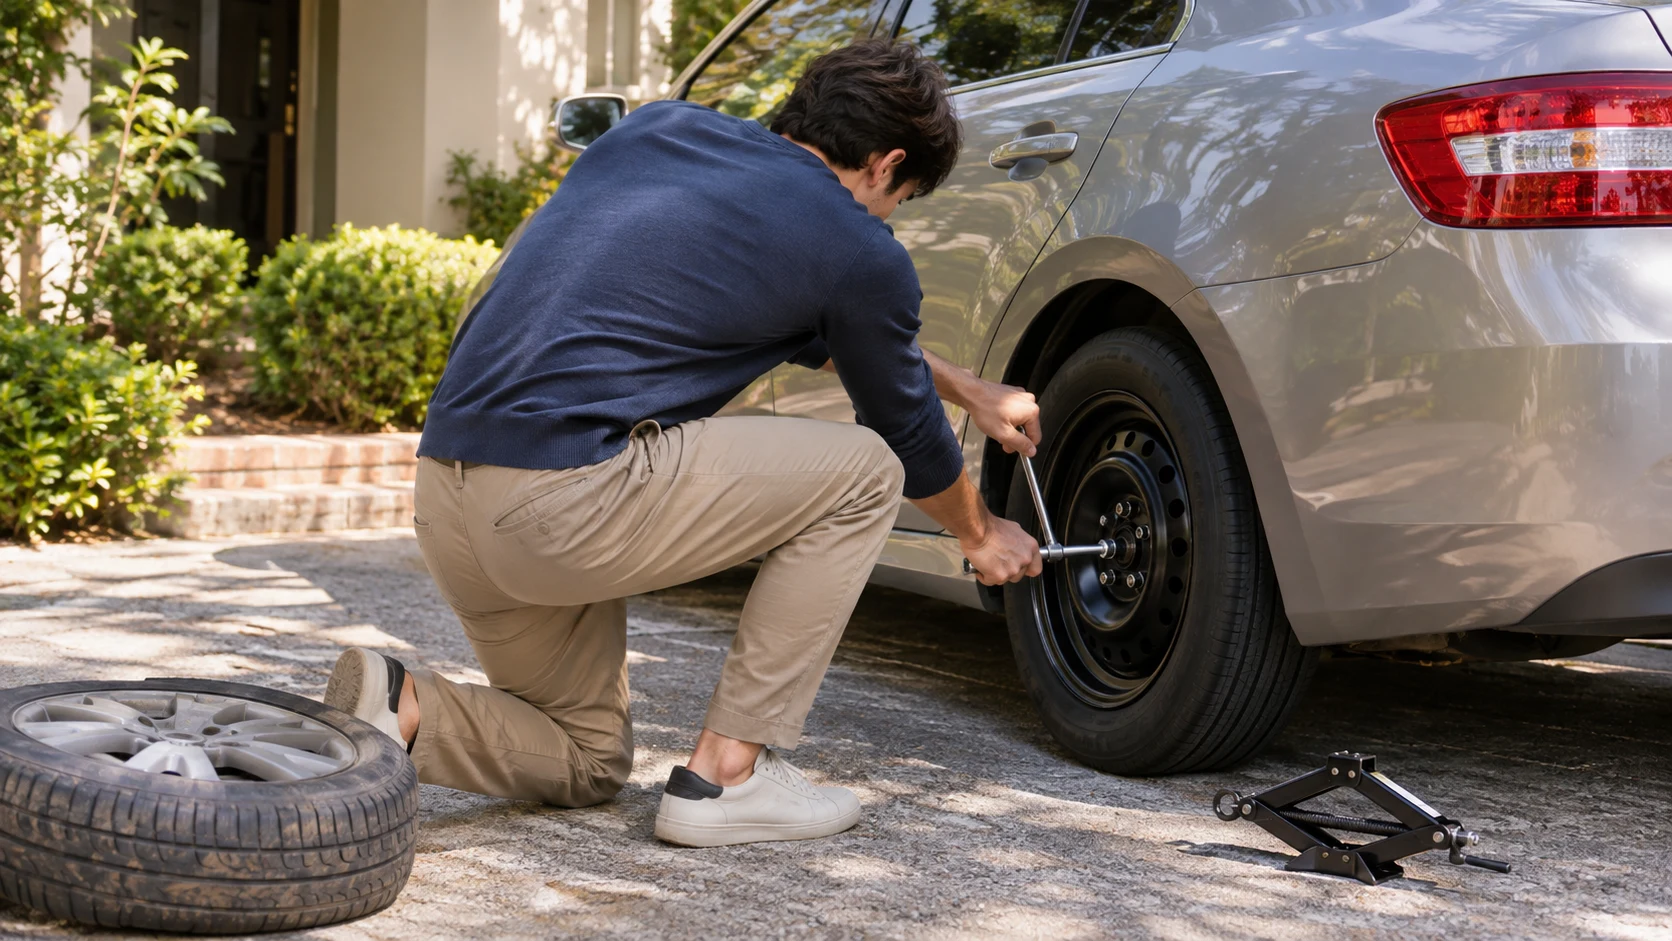
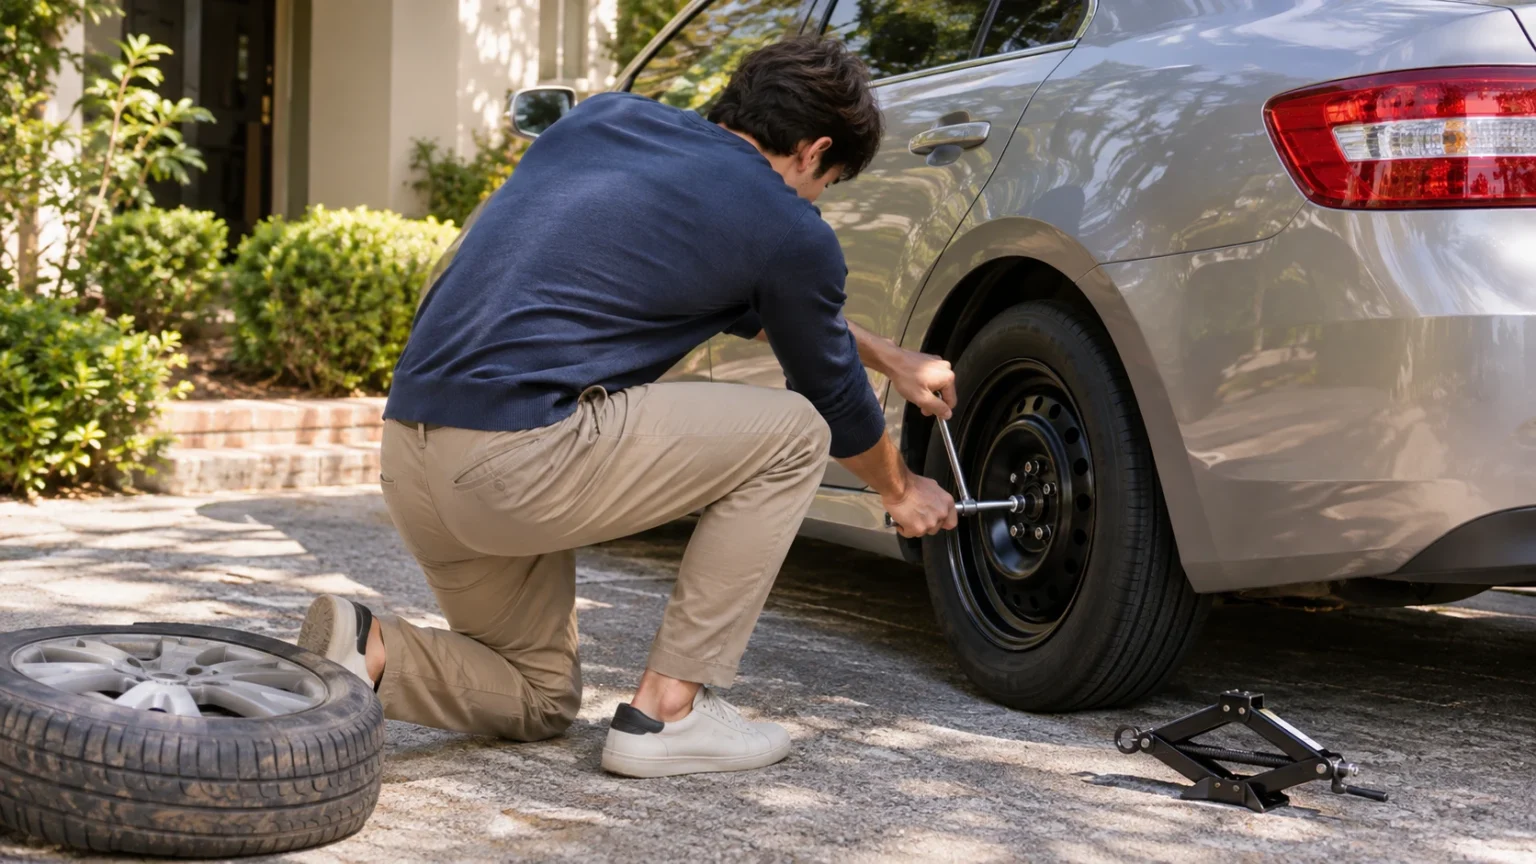
Just because there is a spare tire in your trunk, can you really change a wheel when you get a flat on the road? If you have never done it, you may not even know where to place the jack. Internet services that run on countless servers are no different: having backup equipment and actually holding up through a real failure are two completely different things. That is why some companies deliberately cause failures in services that are running perfectly well, an approach known as ‘chaos engineering’.
Put simply, chaos engineering means ‘a way of building confidence that a system can withstand unpredictable turbulence by running experiments that deliberately cause failures in it.’ The approach became widely known in 2011, when Netflix, then moving to the cloud, introduced a tool that randomly shut down servers serving real customers.
In this article, we will look in turn at why Netflix let a ‘monkey’ loose in its server rooms, the four steps a chaos experiment goes through, how the experiments grew into an army of monkeys, and the principles for breaking systems safely.
Engineering That Creates Failures Instead of Waiting for Them
1. Why Netflix Let a Monkey Loose in Its Server Room
In August 2008, a major database corruption in Netflix’s own data center left the company unable to ship DVDs for three days. Prompted by this, Netflix began moving its service to the Amazon Web Services (AWS) cloud that same year and started designing its systems on the assumption that some of its many servers could fail at any time.
(1) A spare tire is not enough
In July 2011, the Netflix tech blog wrote that having a spare tire does not guarantee you can deal with a flat. To be truly prepared, you would have to puncture a tire in your driveway on purpose and practice changing it; that practice is costly in the real world, but in the cloud it can be automated at almost no cost.
(2) Enter Chaos Monkey
The tool built for this was Chaos Monkey. It randomly picks servers that are serving real customers, shuts them down, and checks whether customers can still use the service without being affected. Its name comes from the image of a monkey loose in a data center, wrecking equipment at random, and in 2012 its source code was released under the Apache 2.0 license.
(3) Breaking things during business hours on purpose
Chaos Monkey ran during weekday business hours, while engineers were watching. The idea was to find weaknesses at a time when problems could be handled immediately, and then fix them so that the system would recover on its own next time without anyone stepping in.
2. The Four Steps of a Chaos Experiment
Chaos engineering is not about smashing servers at random; like a scientific experiment, it is a process of forming and testing a hypothesis. The ‘Principles of Chaos Engineering’, written up by Netflix engineers, describe an experiment in the following four steps.

- Steady State: A measurable indicator, such as throughput, error rate or response latency, that shows the system is running normally.
- Hypothesis: The prediction that the steady state will continue in both the experimental group, where failures are injected, and the control group, which is left as it is.
- Fault Injection: Deliberately introducing events that could happen in the real world, such as servers going down or network connections being cut.
- Control Group and Experimental Group: Comparing the steady state of the two groups to see whether a difference appears that would disprove the hypothesis.
A distinctive feature of these experiments is that they watch the outcome visible from the outside instead of examining every part of the system’s internals. The harder it is to find a difference between the two groups, the greater the confidence that the system can withstand turbulence; if a difference is found, a weakness has been discovered that can be fixed before a real outage strikes.
3. Experiments That Grew into an Army of Monkeys
As Chaos Monkey proved its worth, Netflix built a series of tools for different kinds of failures and called them the ‘Simian Army’. The scope of the experiments also widened from a single server to a data center and then to an entire region.
(1) Slowness is a failure too
Latency Monkey deliberately adds delays to communication between servers to mimic a service slowing down. By making the delay very long, it can test the same situation as a service going down without actually switching off any server.
(2) Rule-breaking servers and unused resources
Conformity Monkey finds and shuts down servers that break best practices, such as those that do not belong to an auto-scaling group, while Janitor Monkey finds and removes unused resources to keep the cloud tidy.
(3) Switching off a data center or an entire region
Chaos Gorilla simulates the outage of an entire AWS Availability Zone, while Chaos Kong takes down an entire Region. Moving Netflix’s service from one region to another first took about 50 minutes, but this was later cut to about 6 minutes.
4. Principles for Breaking Systems Safely
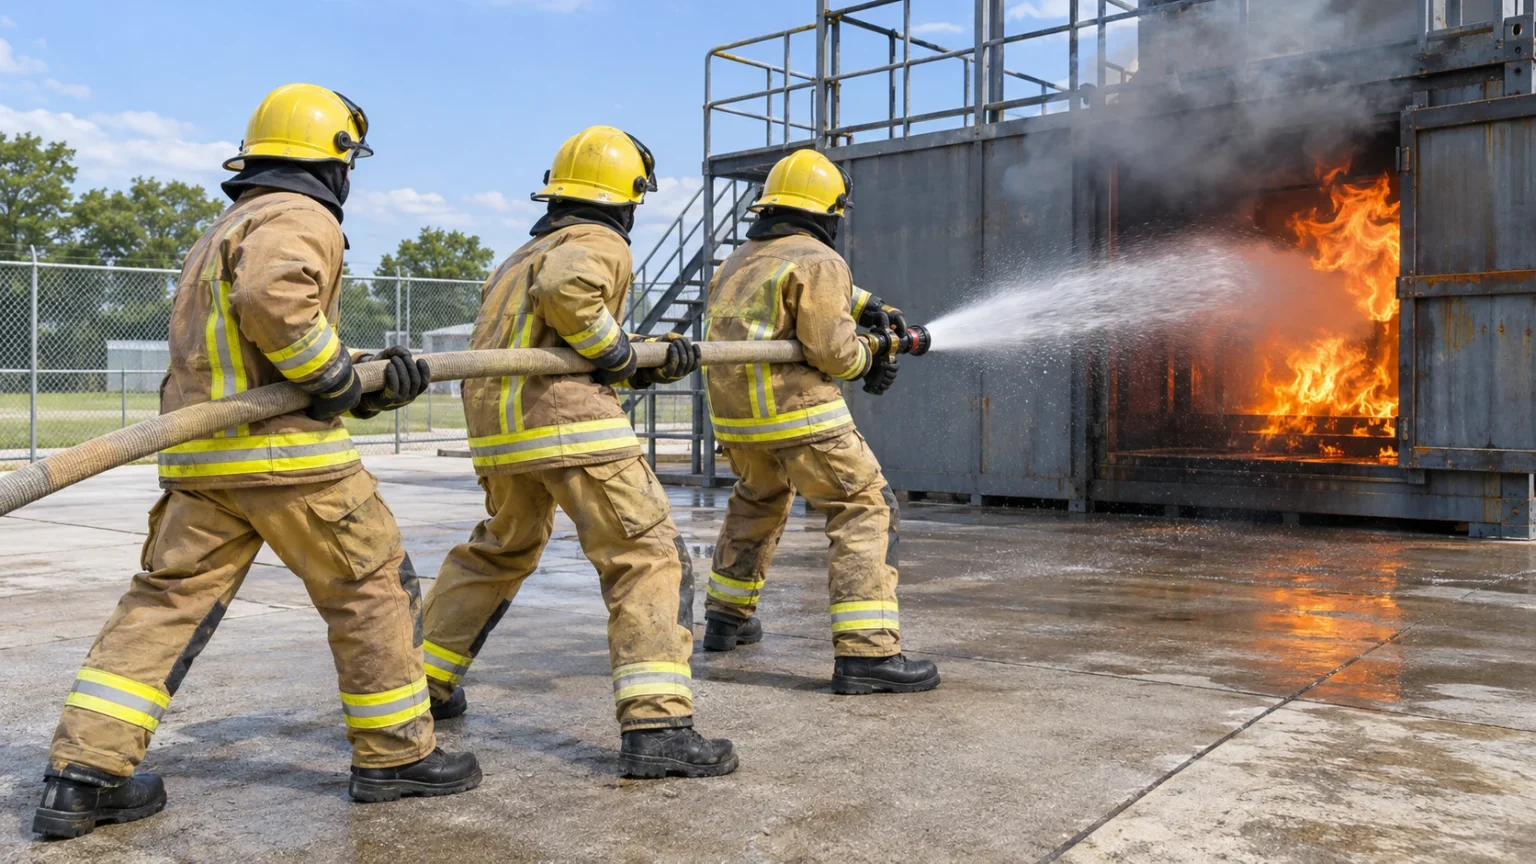
The idea of causing failures on purpose resembles a fire drill. In fact, in 2003 Jesse Robbins at Amazon, inspired by firefighter training, created ‘Game Day’, which deliberately triggered major failures on a set schedule. But just as a training fire must not spread beyond its designated area, chaos experiments come with principles that must be followed.
(1) Minimize the blast radius
Keeping the harm an experiment could do to customers as small as possible is called ‘minimizing the blast radius’. Experiments start small, widen gradually when no problems appear, and must be able to stop immediately if anything looks wrong.
(2) In production, and automatically
Because systems behave differently depending on their environment and traffic, the principles recommend experimenting in the real production environment. And since experiments run by hand are hard to sustain, they also call for automating both the experiments and the analysis of their results so that they can be repeated continuously.
(3) Not only failures but unexpected events
Experiments cover not only hardware failures and software errors but also events that are not failures at all, such as a sudden surge in traffic. Events are prioritized for testing according to how much impact they could have or how often they are likely to occur.
Chaos engineering is less an effort to eliminate failures altogether than an attitude of accepting that failures will inevitably happen and choosing to experience them in advance. Failures cannot be avoided, so it is better to meet them first at a time we choose: that simple idea is the first step toward understanding chaos engineering.